About DoppelGegner

Conversational AI is reaching customers faster than teams can reliably check how it behaves after every change.

Why we exist

DoppelGegner evaluates conversational AI through synthetic, multi-turn conversations. It combines general conversation-quality scoring with customer-specific conformance checks to test whether an agent still behaves as intended.

As prompts, models, and workflows change, DoppelGegner helps verify the requirements that matter to your product and ties each result back to the exact messages that support it.

Worth saying plainly

Our first test subject

DoppelGegner's first deployment tests a recruiting agent built by a company the founders are also involved in. That was deliberate — it was the fastest way to get a real agent, a real rubric and a real set of failures in front of the system.

It is also why the evidence rules are strict. Grading a familiar agent invites generosity, so we built rules that make generosity impossible.

How we handle evaluation

  • Rules take precedenceDeterministic failures cannot be overridden by model judgment.
  • Evidence is requiredFindings without a cited message are rejected.
  • Unscorable is not a passTwo rubric patterns were reported as unscorable rather than quietly passed.

Founders

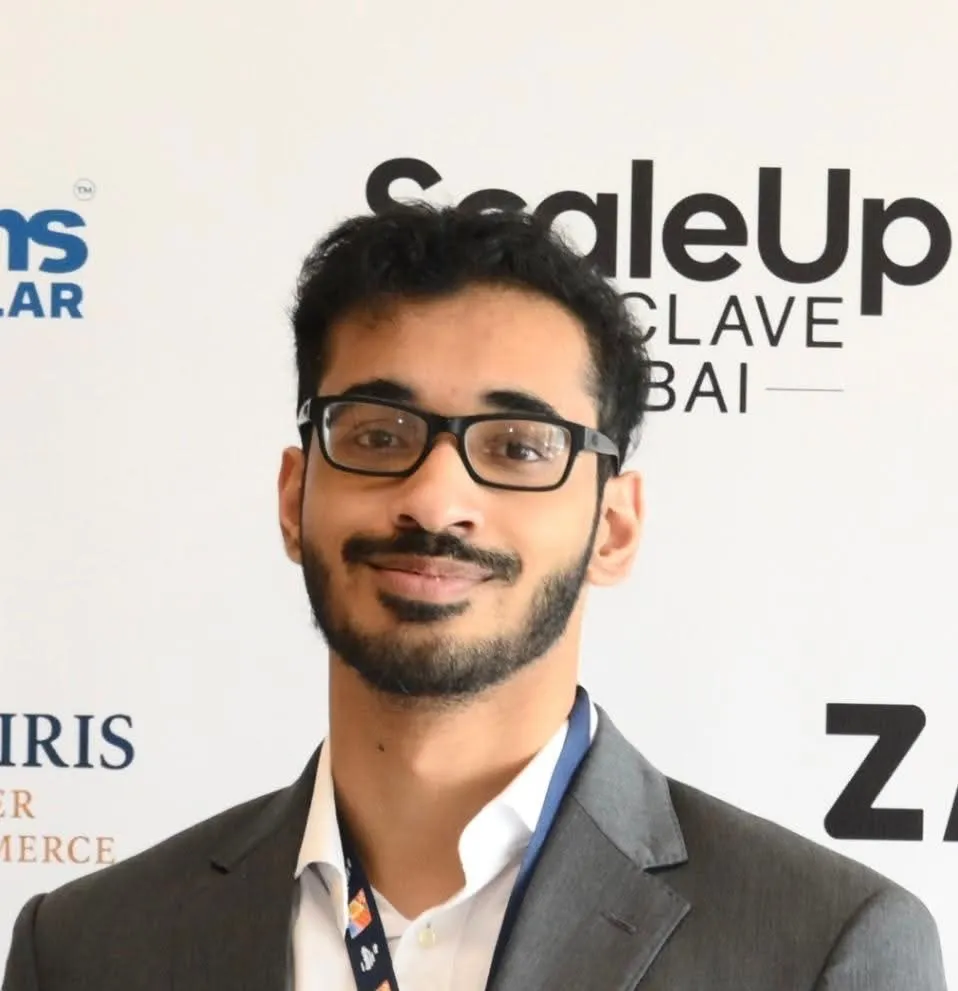
Faaiz Shaphy

Co-Founder

I'm a Computer Science undergraduate at UT Dallas, graduating in December 2026, with a strong interest in building and testing software systems. I'm especially drawn to problems where it isn't enough to say something works — you need to understand how it behaves, where it fails, and what evidence supports the result, and that same focus on evidence shapes my LinkedIn newsletter, Systems. Algorithms. Proof.

My work on conversational AI and evaluation systems kept bringing me back to the same problem: how do you know an agent is actually behaving the way it should? Teams were shipping AI agents that talk to real people, with no clear way to prove those agents behaved as intended. DoppelGegner runs synthetic personas through real conversations with an agent and audits the results against defined standards. Every finding links back to the exact messages behind it.
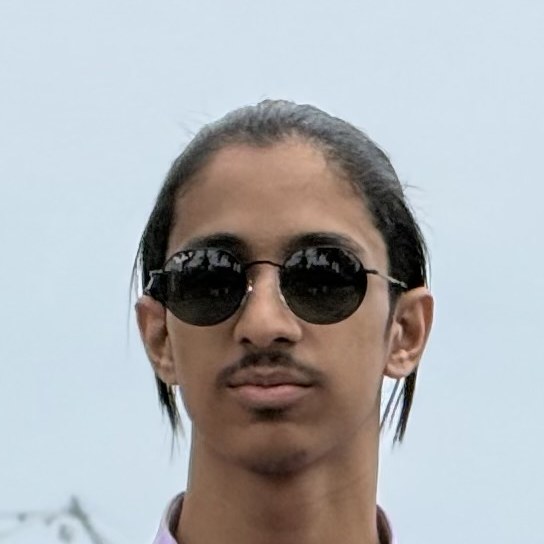
Fawwaz Shaphy

Co-Founder

I have been coding since the start of middle school. Now a high school senior, I've been at the forefront of development for many teams working on a variety of projects. I'm drawn to applied math, physics, robotics, and rocketry.

I like finding where a system breaks by pushing it with math and logic. AI agents can be tested the same way. An agent can look like it works and still fail in the situations that matter.

That's what DoppelGegner is for. It's designed around finding the conversations, behaviors, and edge cases that conventional evaluation misses. I want that kind of testing to be a given step in how conversational AI gets built.

Talk to us

Questions, ideas, or anything else — send us a message.